
Universities have two specific live-caption needs that most off-the-shelf meeting transcription tools don't address well: accessibility for deaf and hard-of-hearing students (often a legal requirement, not a nice-to-have), and language access for international student cohorts where the lecturer speaks one language and the audience reads in several.
The lecture-capture systems that universities already run — Panopto, Echo360, Zoom for Education, Microsoft Stream — solve part of the problem: they auto-caption the recording for the post-lecture replay. What they don't solve well is real-time translated display during the lecture, where a Mandarin-speaking student in the back row reads captions on their phone in simplified Chinese, the English-speaking accessibility student reads source-language captions on theirs, and the deaf student gets a real-time transcript with proper line breaks. (Tools differ in how many languages one live session can carry, and in how much of that choice reaches each student's own screen; that distinction is the crux of the comparison below.)
This guide covers what universities actually need from a live-caption tool, how the setup works on lecture-day, and where each of the realistic options fits — including Subanana (which I run), Wordly, and the lecture-platform-native captioning that's already in your stack.
What universities actually need
Three requirements come up consistently across the universities I've talked to:
- Real-time captions visible to attendees during the lecture, covering the languages the student body needs. Not just for the recording. Students who need captions for accessibility or language reasons need them while the lecture is happening, not 24 hours later. (Whether a tool covers several target languages within one session or needs one session per target language is a real differentiator — see the comparison below.)
- Audio source flexibility. Some lectures are in person with a lapel mic and a PA system. Some are hybrid (lecturer in person, remote students on Zoom). Some are pure online. The captioning tool has to take audio input from whichever source the lecture is actually using.
- No "install our app" friction for students. Asking 200 undergraduates to install an app or sign into an account before each lecture is a non-starter. Browser-based caption display via a link or QR code is the only realistic distribution model for a large class.
Add-ons that depend on the university:
- Accessibility compliance (Section 508 in the US, EAA in the EU, BS 8878 in the UK) for deaf and hard-of-hearing students.
- Integration with existing lecture-capture (Panopto, Echo360) so the live-caption track also lands in the recording.
- Multi-language support sized to actual student body — a small lecture might need 1 target language, a large international programme might need 4.
- Glossary support for course-specific terminology (lecturer's specialist vocabulary, named entities, technical abbreviations).
Setup shapes that work in practice
There are three setup shapes that come up most often. The right one depends on lecture format (in person / hybrid / online), AV equipment, and IT support availability.
Shape 1: In-person lecture, lapel mic, real-time browser captions
Used when the lecturer is physically in the lecture hall, uses a lapel or handheld mic, and the audience is in the room.
- Audio input. Route the mic feed into a laptop running the captioning tool — easiest path is a USB audio interface that taps the AV system's auxiliary output. If the lecture hall AV doesn't have a clean aux out, a backup option is a second lapel mic worn alongside the primary, with its own USB receiver.
- Captioning tool runs on the laptop. For Subanana specifically, the laptop opens the live-session view in a browser, the host (typically the AV team) sets the source language plus up to five translation target languages before the lecture, then starts the session. A cohort that needs several languages at once is covered by that one session on that one laptop, because the targets live inside the session rather than in parallel sessions.
- Audience access. A QR code displayed on the projector (or pre-published in the course LMS) opens the audience caption view in students' phone browsers. Each student then picks the one language they read on their own phone: the original, or any of the targets the host configured for that session.
- Post-lecture artefact. Every live session records the event audio automatically and keeps it in the workspace. For a caption file, the AV team re-processes that recording through Subanana's file-upload transcription, which runs as a fresh project and uses transcription minutes, then attaches its SRT to the Panopto / Echo360 recording for permanent accessibility coverage.
Shape 2: Hybrid lecture, Zoom or Teams for the remote portion
Used when the lecturer is in person but some students join remotely via Zoom / Teams / Meet.
- Audio input. The same mic feed that goes into the platform (Zoom / Teams) also feeds the captioning tool. Easiest path: route the laptop's system audio into the captioning tool via a virtual audio cable (BlackHole on Mac, VB-Cable on Windows). The captioning tool listens to whatever the Zoom call is hearing.
- Captioning tool runs on a second device. Best practice is a dedicated laptop for captioning so the lecturer's Zoom session isn't competing for system resources.
- Audience access. In-room students scan the QR code; remote students get the audience caption link via the Zoom chat or the course LMS.
- Post-lecture artefact. Same as Shape 1: re-process the session's audio recording through file-upload transcription, then attach that project's SRT to the lecture recording.
Shape 3: Fully online lecture, browser-only
Used when both lecturer and audience are remote.
- Audio input. The lecturer's mic feed goes into both their lecture platform (Zoom / Teams / Meet) and the captioning tool. If the lecturer is doing everything on one machine, virtual audio cable routes the Zoom output back into the captioning tool.
- Audience access. Caption link distributed via the course LMS and the Zoom chat. No QR code needed because everyone's already on a screen.
- Post-lecture artefact. Same route as Shape 1: the session's audio recording re-processed through file-upload transcription, its SRT attached to the lecture recording.
Tool options compared (documentation-based)
Three realistic options for universities, with different trade-offs:
Option A: Lecture-platform-native captions (Panopto, Echo360, Zoom Live Transcription)
Strength: zero new vendor relationship; already in your stack; auto-attaches to the lecture recording.
Weakness: built-in captioning is designed first around captioning the recording in the language being spoken. Whether translated captions are available at all, and which languages are covered, varies by platform, by licence tier and by add-on, so check what your institution's licence actually includes before you plan a multilingual cohort around it.
When this fits: lectures where captions in the spoken language cover the need, or where you have confirmed that your licence already includes the translation languages your students read.
Option B: Wordly
Strength: enterprise-grade live translation built specifically for events; 3,000+ language pairs; deep integrations with Zoom, Teams, Meet, WebEx; managed-service onboarding and live event support; MP3 voice dubbing as an add-on for translated audio output; SSO + configurable data storage at the Enterprise tier.
Weakness: pricing is built around prepaid hour packages. Wordly's published starting point is about $1,500 for a 10-hour package, which can be used in any increment for up to 12 months, and your price depends on the number of hours you need; you can purchase by the event or for the entire year. For a university running 50+ lectures per term across multiple departments, that means sizing an hour package up front. And for smaller-scale validation ("can we trial this on one course before rolling out university-wide?"), a prepaid block of hours is a bigger first step than a monthly subscription.
When this fits: large research universities with central AV / accessibility teams, dedicated procurement budgets for enterprise tooling, and event volume that justifies buying hours in advance. → Deep dive: Subanana vs Wordly (2026).
Option C: Subanana
Strength: published per-month subscription pricing (no prepaid hour package); a one-time 5-minute live-caption trial per workspace for a first look; the host configures one source language plus up to five translation targets in a single session, and live minutes debit once by audio duration whatever the target count, so departments can self-serve without central procurement; browser audience captions with no app install; 95+ source languages with best-per-language model routing plus glossary support to lock instructor names, department names, and course-specific terminology.
Weakness: one live session carries up to five translation targets, so a lecture that has to serve more than five reading languages in the same moment sits outside its shape (Wordly handles many target languages natively within a single session); on a student's own phone the caption view shows one language at a time, with two-language side-by-side belonging to the venue-screen projection rather than to personal devices; live captioning is a Max-plan feature rather than something every paid tier includes; no per-platform deep integration with Zoom / Teams / WebEx for the live-caption shape (workflow is audio-input-based via mic or virtual cable); no MP3 voice dubbing of translated text (text captions only); no enterprise SSO or configurable data residency in the published feature set today; smaller language pair breadth than Wordly's 3,000+. For an SRT subtitle track, or DOCX / XLSX / Markdown of the transcript, you re-process the session's audio recording afterwards via Subanana's file-upload transcription, which runs as a new project and uses transcription minutes.
When this fits: universities or individual departments running smaller-volume lectures, validating live-caption fit before committing, or needing multilingual coverage outside Wordly's main use cases. Departments that can't get budget approval for a central enterprise contract can self-fund a Max workspace subscription.
→ Product: Subanana — multilingual live captioning.
Practical workflow: setting up Subanana for a recurring lecture
For a department running a recurring lecture series in one language with students who need captions in another (or in two or three others, all carried by the same session), here's the practical workflow:
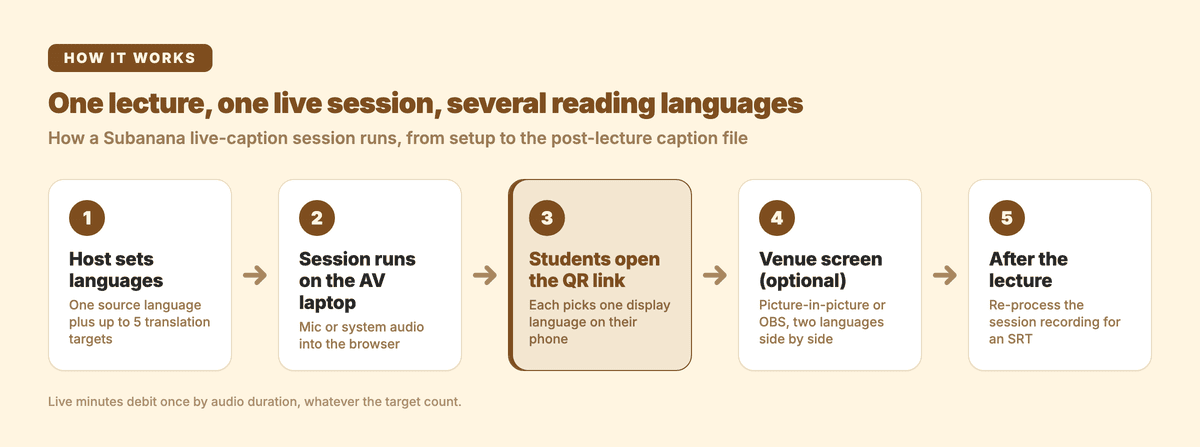
- One-time setup (~30 minutes before first lecture). AV team sets up the audio routing into the captioning laptop (USB interface from AV aux out, or virtual audio cable). Department admin creates a Subanana workspace and pre-configures the source language plus the translation targets the cohort needs, up to five of them in the one session.
- Pre-lecture (~5 minutes). AV team opens the live session, confirms audio level, generates the QR code, prints it on the lecture slide or projects it on a screen at the start of the class. Pre-publishes the audience caption link in the LMS for remote / late-arriving students.
- During lecture. The captioning runs in the background — the lecturer doesn't interact with it. Students who want captions scan the QR or open the LMS link.
- Post-lecture. The session's audio recording is already saved in the workspace. AV team re-processes that recording through file-upload transcription, a fresh transcription billed in transcription minutes, exports its SRT, and uploads that to the lecture-capture system (Panopto / Echo360) so the caption track is attached to the recording for permanent accessibility coverage.
- Across the term. The configured source + translation targets persist per session, so there is no re-setup each time. If the lecture content changes language mid-term (a guest lecturer in Mandarin during a primarily-English course), the host reconfigures the source language on the live-session view before that lecture and switches back afterwards.
Frequently asked questions
Does Subanana integrate with university lecture-capture systems?
Not as a per-platform deep integration — Subanana's live captioning takes audio input from the host's mic, system audio, or a virtual cable. After the lecture, re-process the session's audio recording through file-upload transcription; that project's SRT uploads to Panopto / Echo360 as a caption track for the recorded video, which is the practical integration shape for most universities.
Can Subanana handle accessibility compliance (Section 508, EAA)?
Compliance is determined by what your university's accessibility office requires you to provide for deaf and hard-of-hearing students — typically a real-time caption track during the lecture plus a corrected caption track on the recording. Subanana covers both shapes: live captions during the lecture, and a caption track afterwards from re-processing the session's audio recording through file-upload transcription. Whether that meets your specific compliance framework depends on your university's policy. Subanana doesn't publish formal Section 508 or EAA conformance documentation today, so confirm fit with your accessibility office before relying on it for compliance-critical contexts.
How does language selection work for attendees?
The host sets the source language before the session starts: a session cannot be created without picking one. If the lecturer moves between languages mid-class, the host adds a second spoken language to the same session, up to ten spoken languages in all. Separately, the host sets up to five translation targets. Every attendee who opens the QR or share link then picks one display language for themselves: the original, or any of the targets the host configured. A single session can therefore serve a Mandarin reader, a Korean reader and an English reader at the same time, each on their own phone, each reading one language. Attendees choose from the languages the host configured, so the cohort's languages belong in the session setup. Showing two languages together at once is the venue-screen projection (the picture-in-picture window, or the plain browser-source URL you drop into OBS, vMix or ProPresenter to drive the room's screens), not something an individual student sets up on their phone.
What audio quality do you need for good live captions?
A clean lapel mic feed (close to the lecturer's mouth, away from PA speakers) is the single biggest factor in caption accuracy. Room mics on the ceiling typically produce noticeably worse captions because of room reverb and HVAC noise pickup. If captions matter, prioritise lapel or handheld mic setup over relying on the lecture hall's room-mic array.
Can students download the captions for revision?
The route runs through the event recording rather than the live session view. Each session records its audio automatically and keeps it in the host's workspace. The host then re-processes that recording through Subanana's file-upload transcription, a fresh transcription of the lecture charged in transcription minutes, with one source language chosen for the file, and exports its SRT (or DOCX / XLSX / Markdown of the transcript). Universities typically attach the SRT to the lecture recording in Panopto / Echo360, so students access it as the recording's caption track, which is searchable for revision purposes. Handing the file to students directly works too, if the lecturer wants to.
How does Subanana's pricing scale for a whole department or university?
Subanana's published pricing is workspace-based — a department-level workspace covers the lecturers running sessions from it, and live captioning sits on the Max plan, so that is the tier a department running sessions subscribes to. For university-wide rollout, the workspace structure plus volume discussion is the normal path. Per-session hour-package pricing (like Wordly's model) isn't what Subanana sells; if your procurement specifically needs that pricing shape, Wordly is purpose-built for it.
Related guides
- Subanana vs Wordly (2026): Live Caption Comparison
- Live Captions for Multilingual Events (2026): A Practical Guide
- How to Set Up Multilingual Live Captions for a Webinar (2026)
- Best AI Meeting Transcription Tools 2026: A Documentation-Based Roundup